Cloud- and AI-native environments generate more observability data than traditional VM environments. This scale often leads to sudden metrics cardinality spikes that drive up costs in unpredictable ways.
Cortex XCOR enables teams to optimize metrics by 89% on average while ensuring developers maintain access to high-signal data. While this feature set exists for logs, metrics, and traces, this blog focuses exclusively on metrics. Read on to learn how Cortex XCOR can help optimize your environment’s metrics.
What Causes Massive Spikes in Metrics Cost
Cloud-native architectures have changed how development teams work. By breaking up large, monolithic systems, you create smaller, independent components that are easier to update, maintain and scale. This modularity increases agility, but it also creates a massive observability tax. Each component generates roughly the same amount of metrics data as its VM counterpart, creating a massive spike in total volume (figure 1).
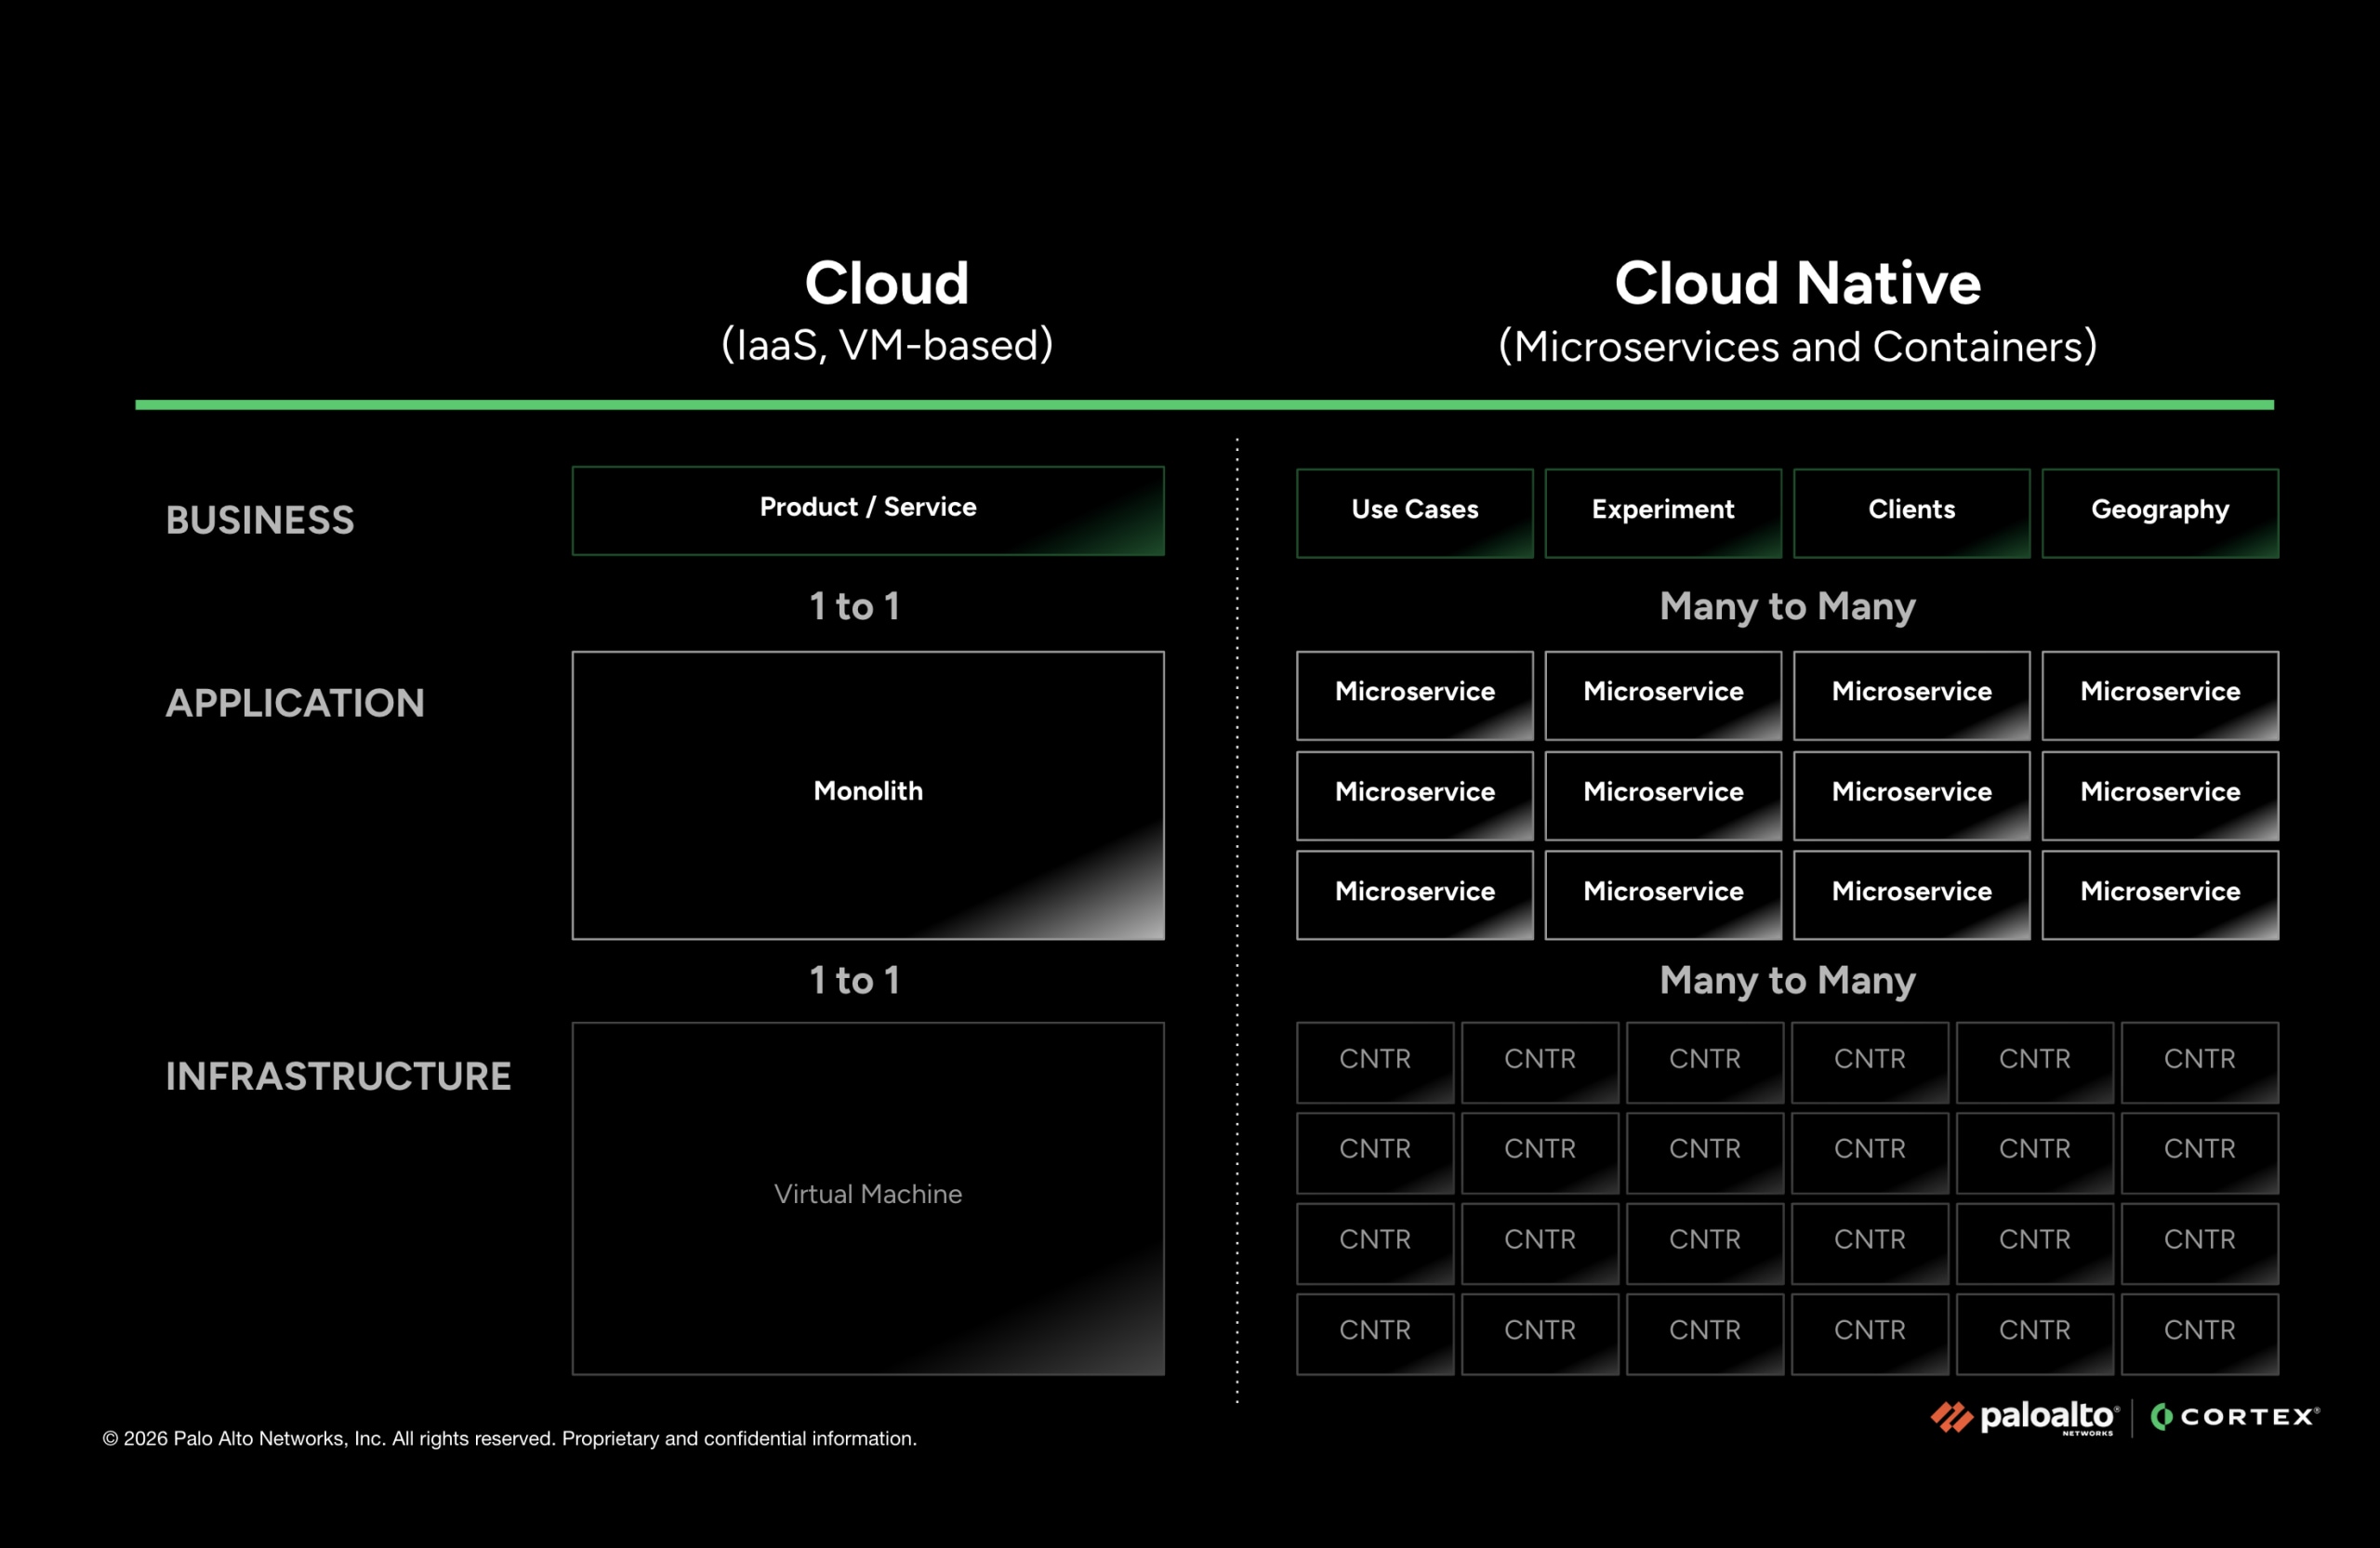
Moreover, cardinality spikes are unpredictable. A developer’s small instrumentation change can unintentionally trigger massive data explosions and cost spikes that are often discovered only after the fact. When costs spiral, teams often launch reactive data-reduction projects. Engineers dedicate sprint time to right-sizing metrics ingestion instead of building the core product.
These projects don’t solve cost problems in a sustainable manner because the teams running them lack visibility into which data is useful for monitoring and troubleshooting. Developers use a fraction of the data that their systems generate. Having access to the right data, however, can be the difference between an issue that’s quickly resolved and an incident that greatly impacts revenue.
So how do you know which data is the right data to keep? Most observability platforms provide little-to-no visibility into which data your teams use. Removing instrumentation blindly creates the risk that developers sacrifice the metrics or labels they need to keep systems up and running.
Cortex XCOR Optimization Engine solves these problems. It enables teams to capture the high-signal metrics needed for monitoring and troubleshooting, so developers no longer have to choose between a budget cap and visibility. Follow these steps to help optimize the metric data for your observability environment.
Clear Unused Data with Recommendations
To gain control over a bloated telemetry environment, start by addressing the most obvious waste — your unused data. Removing this data enables you to see the immediate impact on your observability spend.
The Recommendations screen automatically identifies metrics and labels that have shown zero usage or utility over the past 30 days. Before you commit a change, you can calculate the estimated impact on persisted writes and cardinality within the interface to verify how much volume you’ll save before applying the optimization.
After your review, generate a Drop Rule with a single click, ensuring that the identified metrics no longer are persisted to storage. Immediate removal of unused signals stops the monetization of waste without any risk to your current workflows.
Understand Your Metrics Data Value with Metrics Usage Analysis
After removing the unused data, the next optimization phase requires a deeper analysis about the value of the metrics you’re collecting. Observability vendors provide some transparency into which data is used versus unused. They often provide this insight only for a portion of your metrics footprint. While this information helps make a dent in your observability spending, it doesn’t solve your cost problem entirely.
Right-sizing your metrics footprint requires you to go beyond “used versus unused” and answer the following questions across every metric you collect:
- Is this metric or label being queried?
- How is it being queried?
- How frequently?
- Who is querying it?
Why does this level of granularity matter? Let’s say we’re collecting a metric with high data points per second (DPPS). The same person queried it three times 8 months ago. Other vendors would flag this metric as one your team uses. With deeper visibility, we know it’s not important to our observability practice and can safely drop it.
The Cortex XCOR Metrics Usage feature provides this level of analysis across every metric in your system, down to individual labels. A key part of this analysis is the utility score, which is an aggregate number that indicates relative usefulness determined by:
- Configuration references: Explicit mentions in dashboards, monitors, recording rules and shaping rules.
- Direct query executions: Activity from Metrics Explorer, external sources and unique users.
- Unique users: Metrics queried by more unique users receive a higher utility score than metrics queried repeatedly by a single user.
By identifying metrics with high DPPS but low utility, teams can confidently prune their data for long-term cost savings. For example, the container_memory_swap metric might show high volume and thousands of unique label values, yet have a utility score of zero. Identifying these signals enables you to reshape your data strategy without impacting the developer experience.
Reshape Your Data with Cortex XCOR Optimization Rules
Cortex XCOR Optimization Rules offers multiple ways to reshape data rather than to simply delete it. Teams to retain the signals that deliver the most visibility per dollar spent.
- Drop Rules omit incoming metrics based on specific labels or values before they’re stored.
- Rollup Rules drop unneeded labels — like instance or pod — after metrics are sent but before they’re stored, reducing the cardinality footprint. They keep the analytical value of the metric while removing unnecessary high-cost, high-cardinality labels.
- Mapping Rules downsample in-memory metric data on the streaming ingest path before it’s stored. For example, you might unnecessarily scrape a metric every 5 seconds, where Mapping Rules helps reduce the resolution, scraping every 60 seconds instead.
These rules are applied centrally, so your team doesn’t need to change instrumentation or redeploy services.
Reduce Cost, Boost Signal and Improve Query Responsiveness
Let’s summarize our approach. Cortex XCOR actively analyzes how your team uses observability data. With this analysis, the Recommendations feature surfaces your unused data to remove it for immediate cost savings. For data with nonzero activity, Usage Analyzer helps you understand the true value of the rest of your data. From there, you can apply Optimization Rules to right size your metrics, logs and traces.
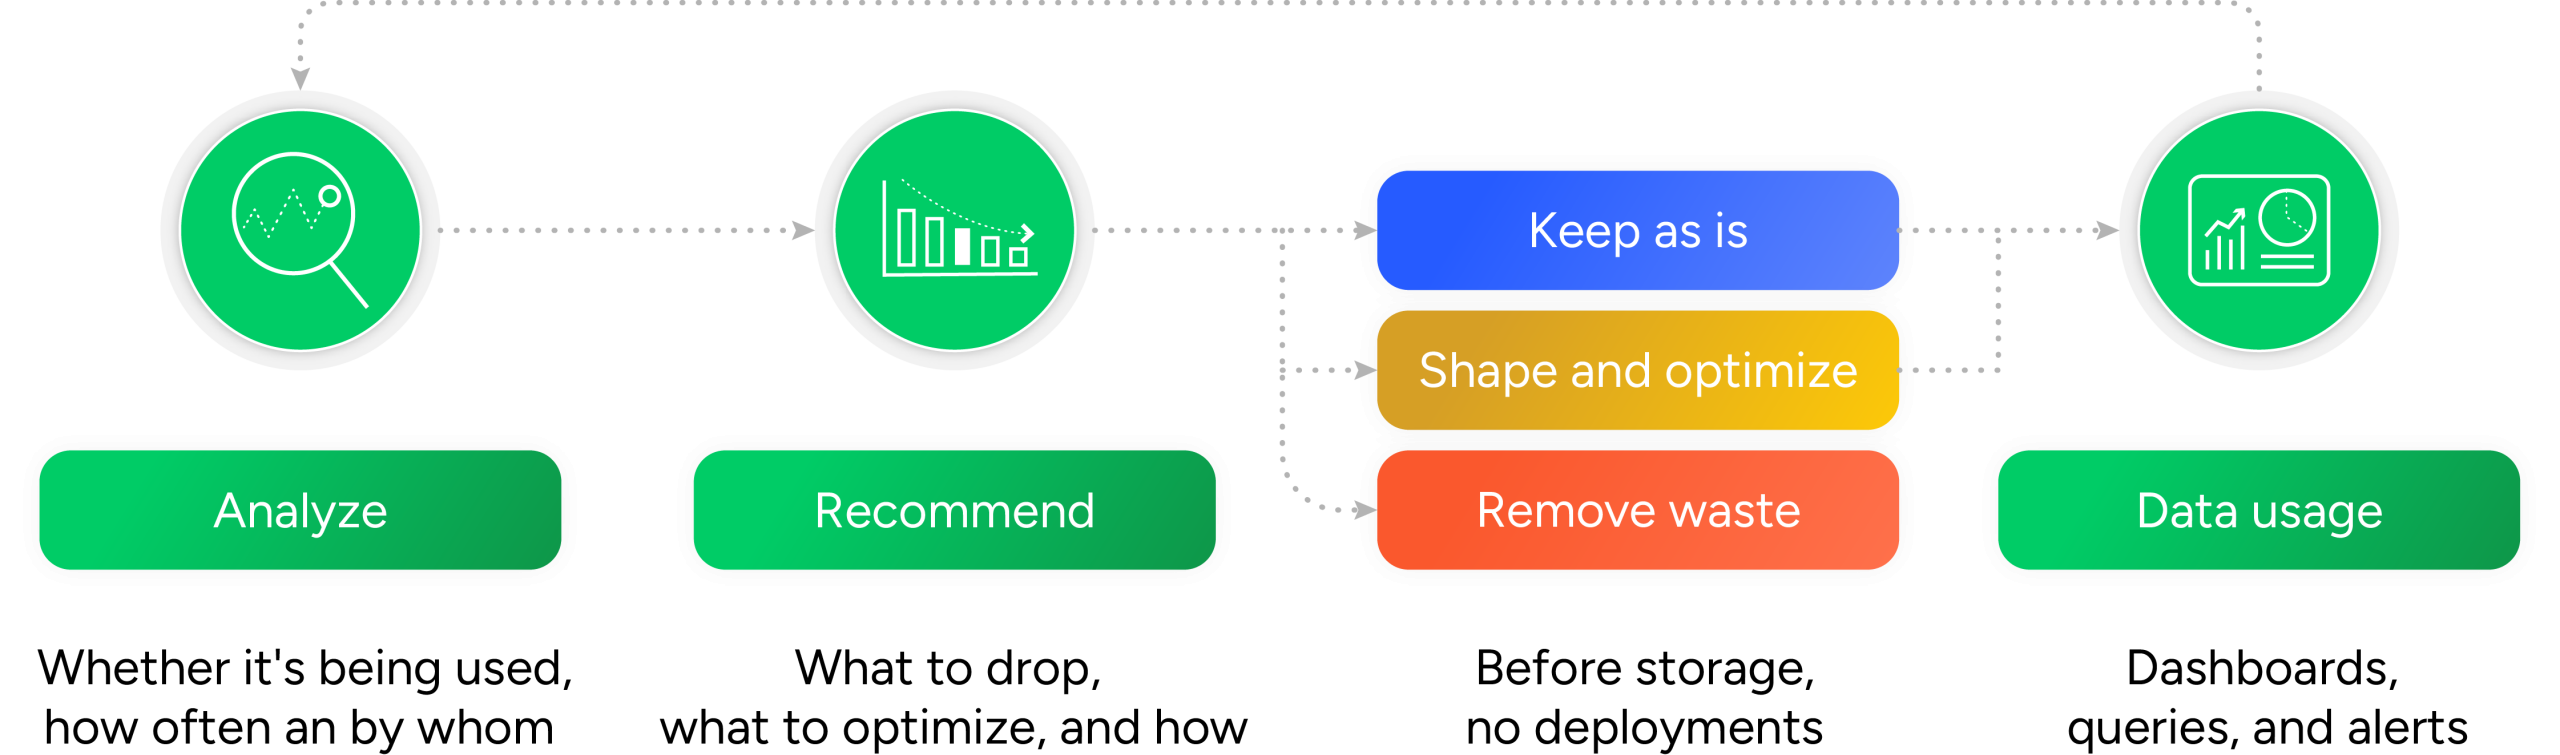
By optimizing for high-value data, Cortex XCOR customers ensure developers always have access to high-signal data when they need it most. They achieve an average 89% reduction in metrics data volume. This efficiency enables organizations to invest more in visibility where they need it and spend less time fighting to justify their observability costs.